Solutions

Full-stack AI Agent infra for edge deployment

Co-optimize harness, model, inference, and hardware. Right-sized capability, bounded cost.

LayerEcosystemIsolated issues

HarnessOrchestration

LangGraphOpenHandsClaude Agent SDK
Process bloat

Task flow and scheduling stay apart Repeat handoffs, manual switches

ModelCapability

DeepSeekGLMQwen
Capability mismatch

Oversized large models Small models fall short

InferenceRuntime

FireworksTogetherSGLang
Runtime mismatch

Model, engine, and chip stay siloed VRAM and concurrency unused

HardwareCompute

NVIDIAAscendIntel
Capacity mismatch

Config does not match real load Overbuilt, or short at peak

Four layers, as one. Intelligence in the work.

Aeloon · Aether Edge AI Agent Infra · AetherStation

From harness to hardware. Fold scattered work into one box.

Aeloon · Aether Edge AI Agent Infra · AetherStation

One software base. Two deploy choices.

01 / Domestic (Xinchuang)

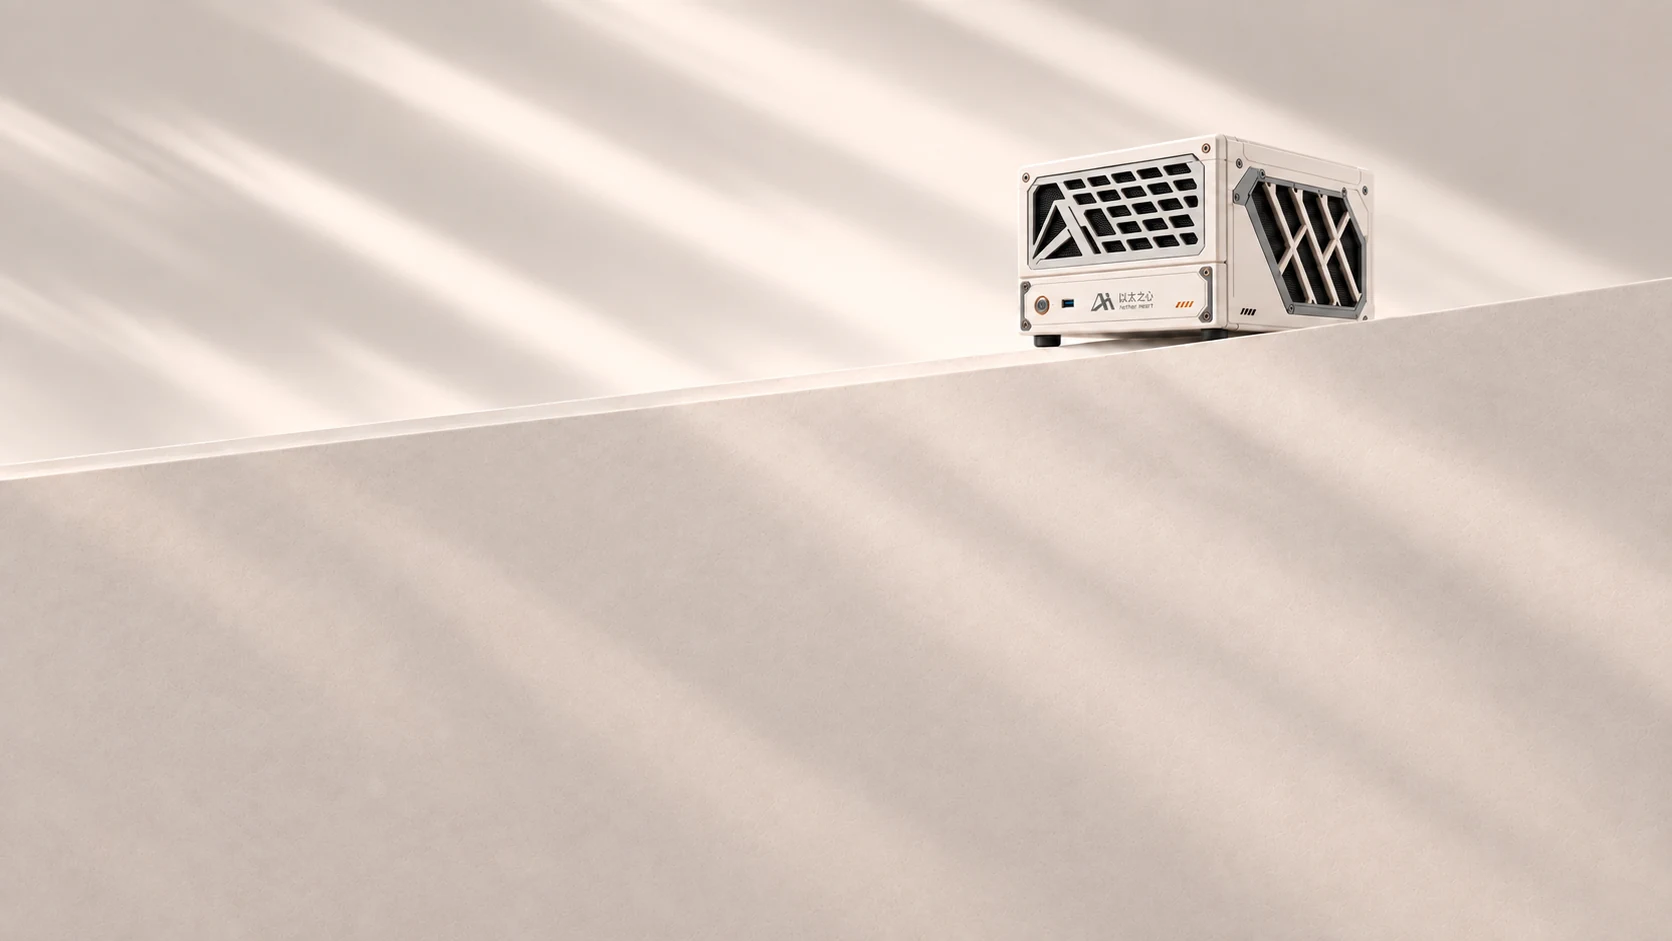
AetherStation

Domestic

Xinchuang Agent Appliance

¥ 32,999

Full-stack domestic chips · Data on-prem Gov / Finance / Healthcare

Core config

Moore Threads / Hygon / Iluvatar More domestic accelerators

Typical uses

Gov docs · Finance review Medical analysis · Factory KB

02 / Standard (NVIDIA)

AetherStation

Standard

High-perf Agent Workstation

¥ 29,999

CUDA ecosystem · High-perf inference Developer-friendly

Core config

NVIDIA/AMD GPU + AetherInfer Qwen3.6-27B: 120 / 16-way 630 tok/s 35B MoE: 20 concurrent (≤50 people)

Typical uses

Code agents · Analytics Workflows · Assistants

COST PER COMPLETED TASK

Measure AI cost from one finished task.

100 active staff · ~2M workflows a year Attune-verified equivalent agent workflows; relative cost as modeled.

1.0×

6× AetherStation · Qwen 27B

Cost per finished task

Ops overhead: Low

Upfront cost: ¥180,000

OptionCost per finished taskOps overheadUpfront cost
  • 8×A100 · Qwen 27B30–40×Medium¥900k–¥1.2M
  • 8×H100 · Qwen 27B11.9×High¥2.2M–¥3.0M
  • GLM-5.2 · Official API11.7×LowAPI usage fees
  • 12×B300 · NV-opt · GLM-5.210.3×High¥10M+

*Note: theoretical comparison under stated task, model, concurrency, hardware, and price assumptions. Structure only; actuals vary.

COMPOUND OPTIMIZATION

Efficiency multiplies in co-optimization.

Optimize software and hardware around the same enterprise task.

Why is AetherStation's cost efficiency so outsized?

Compound Optimization Effect1.54 = 5

AI Efficiency = Harness × Model × Inference × Hardware

Co-optimization multiplies four layers, not a hardware bump alone

  • HarnessLive scheduling
  • ModelTask-fit models
  • InferenceEngine opts
  • HardwareHardware fit

SIMPLIFY THE DELIVERY

Make delivery a standard product.

AetherStation compresses the FDE chain into a product

Classic FDE · 9 steps

  1. Define
  2. Data
  3. Hardware
  4. Model
  5. Infer
  6. Serve
  7. Agents
  8. Integrate
  9. Launch
9 steps5 steps

AetherStation

Covers hardware, model fit, inference, serving, and agent orchestration. Teams return to the work itself.

Aether Heart · 5 steps

  1. Define
  2. Data
  3. AetherStation
  4. Integrate
  5. Launch

SMALL MODELS. COMPLEX TASKS.

Let local small models handle complex work.

15 industry tasks, 13 full marks

Workflow pass rate (%)

  1. Compliance
  2. Transcript
  3. Smart home
  4. Vehicle
  5. Gov routing
  6. Routing
  7. Ops tickets
  8. Contract
  9. Medical
  10. Industrial
  11. Quality
  12. Credit
  13. Claims
  14. Expense
  15. Robot

PERFORMANCE IN PRODUCTION

Performance, on the factory floor.

Single-request throughput
Spark · no MTP9
Spark · with MTP21
AetherStation Lite60
AetherStation Standard125
Unit: tok/s
16-way total throughput
Spark · no MTP128
Spark · with MTP230
AetherStation Lite330
AetherStation Standard630
Unit: tok/s
13.9×
Single-request gain125 tok/s vs 9 tok/s
4.92×
16-way throughput gain630 tok/s vs 128 tok/s
630
tok/s · 16-way totalAetherStation Standard

Our edge: hardware, engine, and scheduling lift throughput together